Luther Monson, Founding Engineer at Gas City

Luther Monson

Open Source · AI · Containers · VMs · Kubernetes · Windows · Go by way of PHP

Operating the One-Box ePHPm Setup: Backups and Blue/Green

Day-two work on the single-VM ePHPm box: a golden AMI that smoke-tests itself, an S3 backup that survives on a box too small to hold two copies of the database, and a blue/green upgrade that moves the data instead of the disk.
7-Minute Read

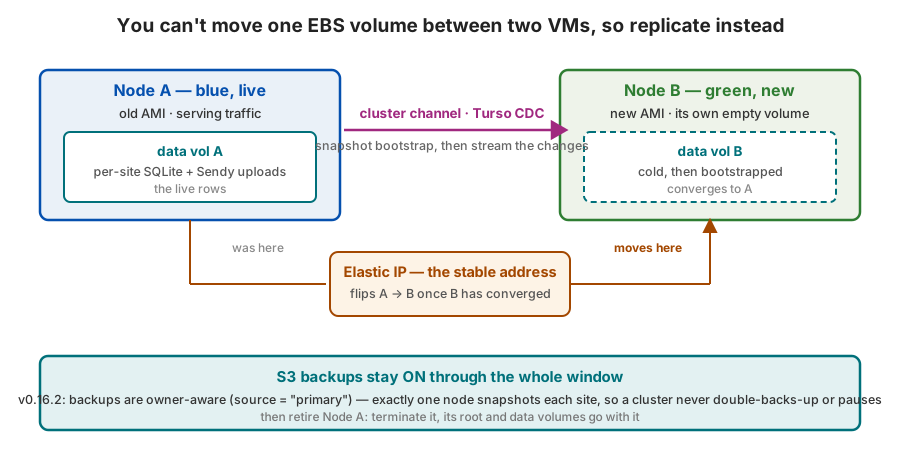
Node A holds the live data; a green node B comes up with its own empty volume; each site's SQLite replicates A to B over the cluster channel with Turso CDC; once B converges the Elastic IP moves and A is retired, while S3 backups stay on because exactly one node takes them

The box is baked, not configured in place. Packer builds a Debian 12 AMI with the ePHPm binary and all three apps’ code already on disk. The source gets pulled from the three private GitHub repos’ tarballs at build time and run through composer install right there in the image. Rolling new code means baking a new AMI.
Replacing a k3s Cluster With One ePHPm Process

How three PHP sites, their databases, cron and backups collapse onto one small VM, and what that costs once you match the bill to the size of the problem.

8-Minute Read

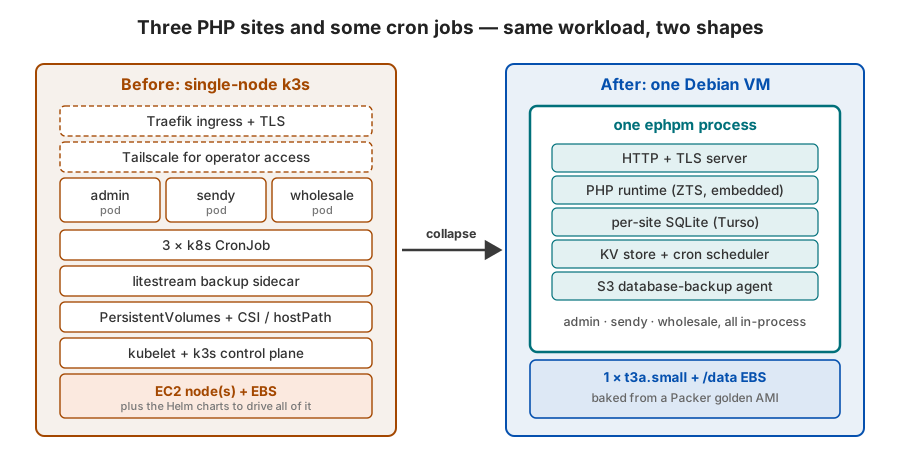
A tall single-node k3s stack of Traefik, Tailscale, three PHP pods, three CronJobs, a litestream sidecar, PVs and the control plane collapses into one Debian VM running a single ephpm process that is the web server, PHP runtime, per-site SQLite, KV store, cron scheduler and S3 backup agent

A couple of weeks ago I wrote up surviving a node rebuild on single-node k3s. Put the stateful bytes on a dedicated EBS volume, treat the node as cattle, and rebuild the machine without losing the data. It works.

Dagger on ephemerd, and a Warm Cache on Throwaway Runners

A fresh engine per job means a cold cache every job — unless the cache lives on the node instead of in the engine. Benchmarked: an ephemeral BuildKit engine warms itself to within a few seconds of a long-running one, no persistent engine required.

10-Minute Read

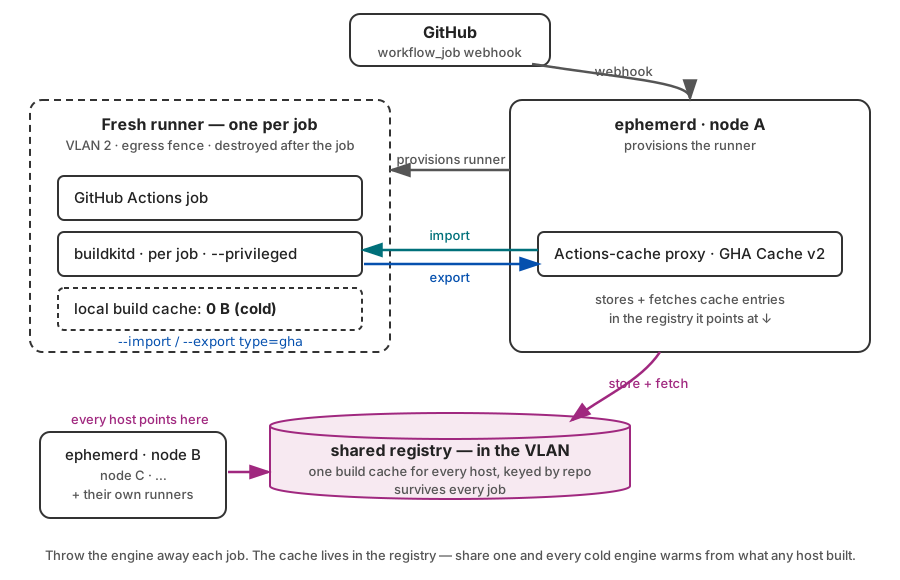
GitHub fires a workflow_job webhook at ephemerd on the node, which provisions a fresh VLAN-isolated runner that is destroyed after the job. Inside it a cold per-job BuildKit engine imports and exports cached layers over the GitHub Actions Cache v2 protocol to ephemerd's Actions-cache proxy, which persists the cache in a registry; point one shared registry in the VLAN at every host for a single fleet-wide cache.

A friend asked me whether Dagger replaces ephemerd. It doesn’t — they sit at different layers, and I wrote half this post explaining that before I noticed the more interesting question hiding underneath it.

Surviving a Node Rebuild: A Durable ePHPm Blog on Single-Node k3s

A compact ePHPm WordPress blog on one k3s node, with its SQLite file and uploads on a dedicated EBS volume. Rebuild the whole node and the data comes back.

11-Minute Read

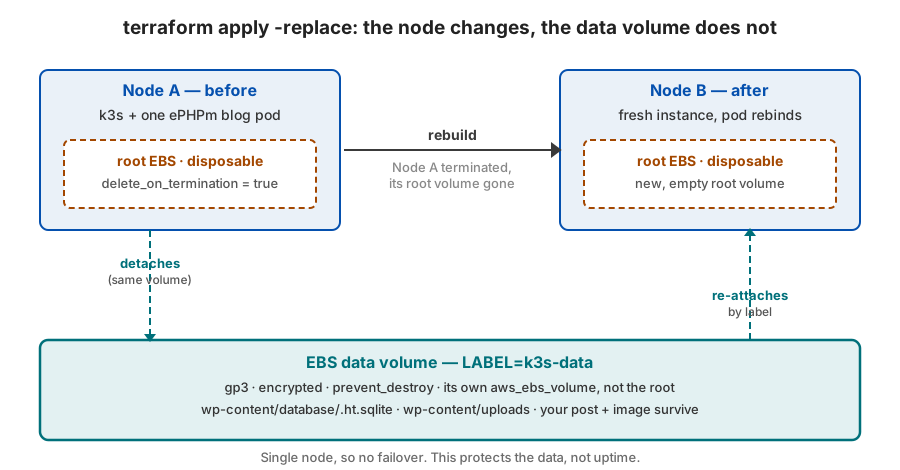
A node rebuild: Node A is replaced by Node B, each root EBS volume is disposable, and the separate labeled EBS data volume detaches from the old node and re-attaches to the new one so the ePHPm blog's SQLite file and uploads survive

A single ePHPm binary runs a whole WordPress site. No php-fpm, no Redis, no MySQL. The database is a SQLite file. I covered that setup in Zero-Dependency Deployments. It makes for a tiny blog: one process, one file, a distroless image around 270 MB. That fits a micro VM with room to spare.

Docker-in-Docker in CI Without Handing Jobs Root

ephemerd runs Docker-in-Docker for container: jobs without a privileged container. Here is what a job could still reach, and the four PRs that closed each hole.

8-Minute Read

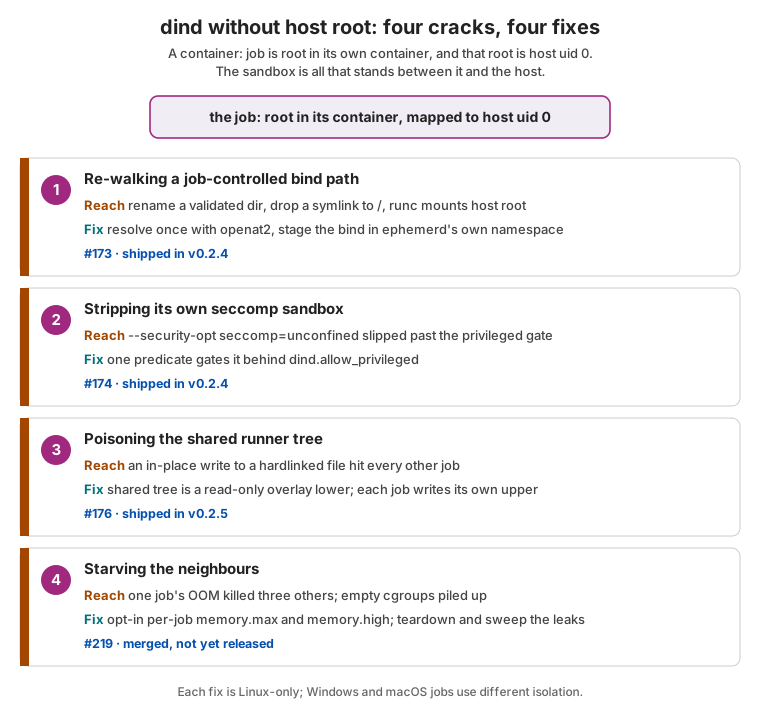
Four dind sandbox cracks and the ephemerd PR that closed each one

ephemerd runs a fresh GitHub Actions runner per job. Some of those jobs need Docker. A workflow builds an image, runs a service container, or uses the container: key. The usual way to give a self-hosted job Docker is Docker-in-Docker, or dind.

Cache Proxies for Ephemeral CI Runners

A fresh runner per job starts with an empty cache. Here is how ephemerd caches Go modules, Packagist, GitHub releases and the Actions cache on the node instead of re-downloading them every job.

10-Minute Read

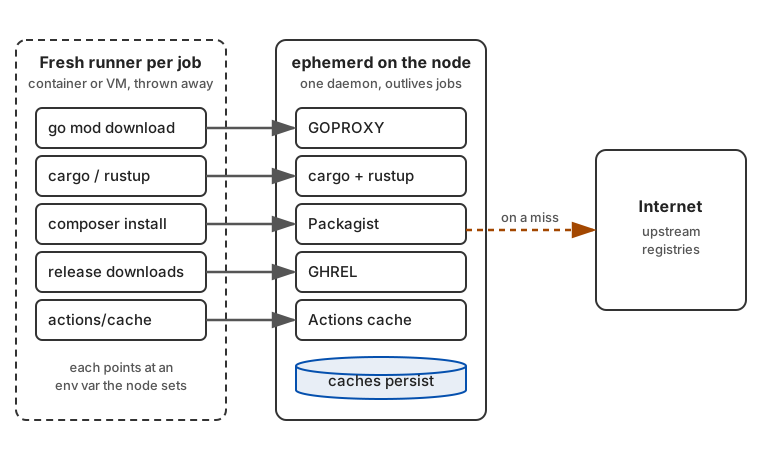
A fresh runner per job points go mod, cargo, composer, release downloads and actions/cache at matching cache proxies on the ephemerd node, where the caches persist and only reach the internet on a miss

ephemerd gives every CI job a brand new runner. A new container on Linux, a new VM on macOS and Windows. The job runs, the runner is thrown away, and the next job starts from a clean image. That is the whole point. Nothing a job does can leak into the next one.

Ephemeral macOS Runners: A Fresh VM Per Job on Apple Silicon

How ephemerd runs each macOS CI job in a throwaway Virtualization.framework VM, and the slot leaks and disk limits I had to fix to make it reliable.

9-Minute Read

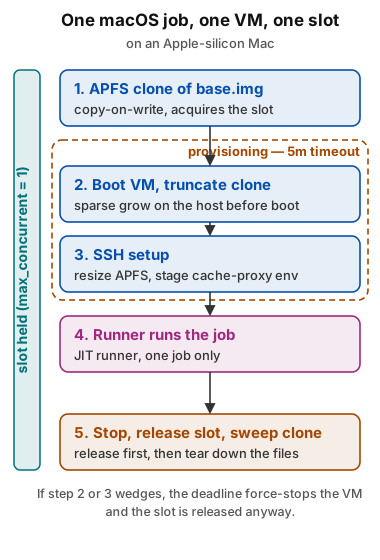
A macOS CI job lifecycle: clone the base image, boot and grow the disk, set up over SSH, run the job, then stop and sweep, with a band showing the single slot held the whole time

ephemerd gives every CI job a brand new environment and throws it away after. On Linux and Windows that environment is a container. On macOS it can’t be. Apple’s license wants macOS running on Apple hardware, so the Mac in my rack is the real thing. The isolation comes from a VM instead.

Thirty-Two Connections and an Empty File: A Race in Turso's Page-1 Allocation

Why concurrent first writes to an empty database could panic Turso, and the fix.

6-Minute Read

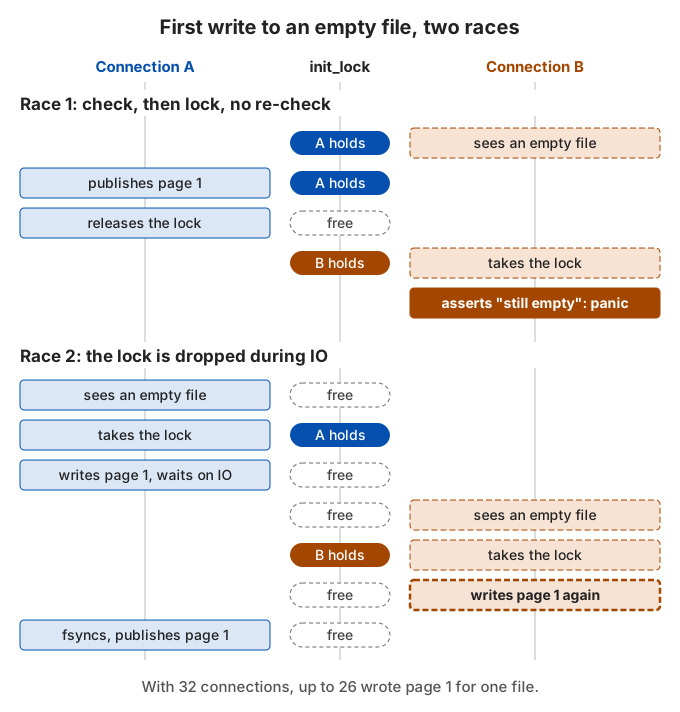
Sequence diagram of two connections and init_lock: in race 1, B checks for an empty file, A publishes page 1 and releases the lock, then B takes the lock and panics on its assert; in race 2, A's lock is dropped while page 1 is being written, so B takes it and writes page 1 again

ePHPm runs PHP inside a Rust server. For SQLite-style databases it uses Turso, a rewrite of SQLite in Rust that is still labeled beta. I recently hammered ePHPm’s per-site mode with brand-new sites. A burst of first requests to a new site could panic inside the engine. This post is about where that panic came from and how to fix it. How Turso got into ePHPm is in Clustered SQLite, Part 2.

Fourth Place in Worker Mode, and Why It Wasn't PHP

ePHPm placed fourth in worker mode on the Yii3 benchmark. The slow part was the Rust layer, not PHP. Six changes in v0.12.0 made it 13% faster on 57% less memory.

10-Minute Read

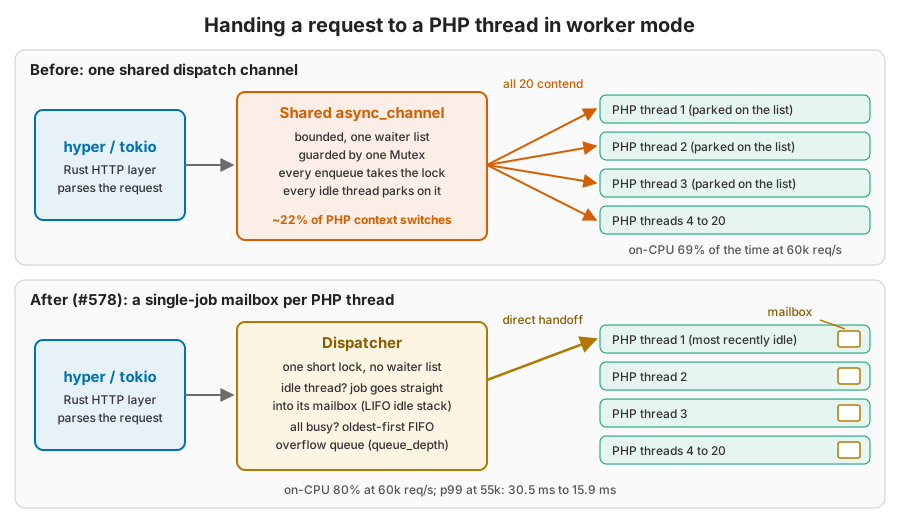
Diagram: before, hyper/tokio hands each request to one shared bounded channel whose waiter list all 20 PHP threads contend on; after, a dispatcher hands the job straight into the mailbox of the most recently idle PHP thread and only queues it in a FIFO overflow queue when every thread is busy

We added ePHPm to the Yii3 runtime benchmark. It runs the same Yii3 API app on a bunch of PHP runtimes and compares them. Our fork with the ePHPm runner is ephpm/app-api.

Composer Without PHP: Embedding vivacity in ePHPm

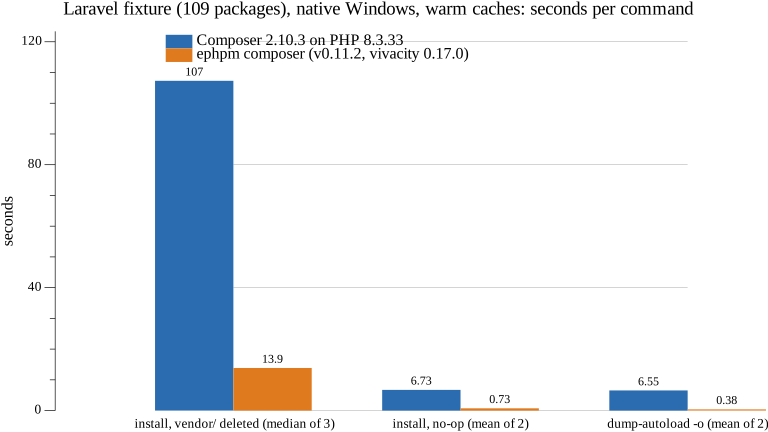
I embedded vivacity, a pure-Rust Composer-compatible installer, in ePHPm so one binary can install a PHP app's dependencies without PHP. This is what it took upstream and in ePHPm, and how it does against Composer on Windows.

10-Minute Read

Bar chart comparing Composer 2.10.3 and ephpm composer on a Laravel install on native Windows

The pitch for ePHPm is one binary in place of php-fpm, nginx and Redis. There was always a hole in it though. To deploy a PHP app you still need to run composer install. That drags PHP and composer.phar back onto the box or into the container build, just for that one step. ephpm composer install now runs a pure-Rust, Composer-compatible installer called vivacity inside the ePHPm binary. One binary serves the app and installs its dependencies. On Windows that works with no PHP installed at all.…

Recent Posts

Categories

About

Luther is a 20+ year software veteran specializing in backend APIs and architecting products. Founding engineer at Gas City building open-source AI software factories on Beads, the durable work graph for coding agents.